Move Any Data Into Apache Iceberg
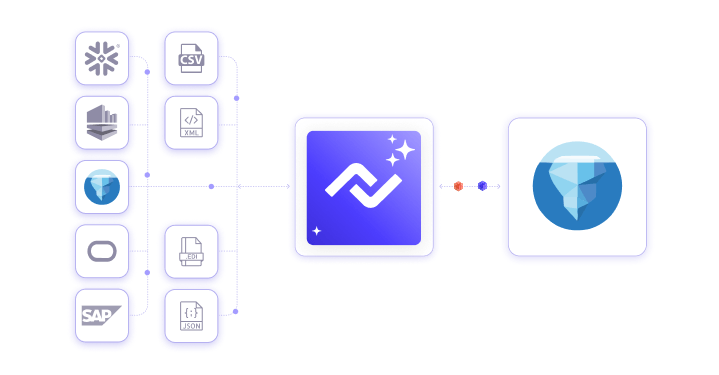
Ingest data from 1000+ sources into Apache Iceberg with no code, real-time CDC, schema evolution, time travel support, and direct Iceberg writes up to 3+ GB/s. No Spark tuning. No Kafka overhead.
Connect to any structured or unstructured data sources using 1000+ bidirectional connectors, or any REST or SOAP API. Nexla automatically creates Nexsets, virtual data products that make any data ready to use and share.
Integrate any data using any style – ETL/ELT/R-ETL, iPaaS, streaming, (S)FTP, or agentic RAG, at any speed, and do anything you need to do as you move data to or from Iceberg and other sources and destinations.
Connect to AWS Glue, AWS S3 Tables, Hive Metastore, and REST Catalog today and instantly start to load or extract data at any speed with proven petabyte scale in production. Databricks Unity Catalog, Snowflake Polaris, and Nessie coming soon.
GB/s throughput
Loaded in under 30 min
Memory
Connectors enable every enterprise function
Connect to any sources or migrate from existing Avro or Parquet data lakes with ease! Just connect. Nexla does all the mapping and movement for you.
Enable less technical staff to integrate Iceberg on their own, without coding, and without needing to deal with any integration or Iceberg complexity.
Build pipelines for Iceberg 10x faster than the alternatives. How? Because Nexla uses AI to do most of the work for you.
Access any structured or unstructured data and any system with the same integration platform using 100s of bidirectional connectors and any API.
Build a medallion architecture in minutes. Nexla generates data products for bronze, silver, and gold layers that can automatically load Iceberg.
Choose from leading Iceberg implementations, integrate them together, or migrate between Iceberg deployments at any time.
Support all your data science and large-scale analytics workloads. Capture data from operations in real-time using change data capture (CDC) or batch. Load it into your data lake with ACID guarantees. Easily build a medallion architecture. Then run your workloads using both batch and streaming data processing.
Move from proprietary to open data storage. Move data directly into Iceberg from source systems. Build a medallion architecture with bronze and silver tiers in Iceberg. Or implement tiered storage with Iceberg holding specific data domains or time periods. Then, leverage your data warehouse of choice as a compute engine with Iceberg tables.
Power live dashboards with fresh data. Capture source data using CDC, streaming, and APIs. Leverage stream processing to turn raw data into business insights. Stream the results directly into Iceberg tables. Then use your BI tools of choice to deliver real-time insights.
Use different Iceberg deployments as sources for machine learning (ML) and generative AI (GenAI). Build agentic RAG pipelines in minutes using Iceberg as context, or build pipelines that prepare data for ML algorithms, all without coding.
Enable decentralized data ownership across Iceberg and other sources. Nexla lets you represent all data, including Iceberg tables, as data products. Share data across teams in Nexla’s marketplace while maintaining governance and quality.
Meet all your regulatory requirements and auditing needs using Nexla and Iceberg. Leverage Iceberg’s versioning with immutable history and point-in-time snapshots combined with Nexla’s audit trails and end-to-end lineage for compliance reporting and auditing.
Nexla currently supports AWS Glue, AWS S3 Tables, Hive Metastore, and REST Catalogs for Apache Iceberg deployments. Support for Databricks Unity Catalog, Snowflake Polaris, Apache Polaris, and Nessie is also planned.
Yes. Nexla supports real-time Change Data Capture (CDC) for Apache Iceberg with exactly-once semantics, automatic schema evolution, and both insert-only and upsert modes. Nexla also supports multi-table CDC consolidation, allowing teams to combine changes from multiple source systems into a unified lakehouse architecture.
Nexla’s high-performance snapshot pipeline can load data into Apache Iceberg at speeds ranging from 1.2 to 3+ GB/s. A 2TB snapshot can typically be completed in 12 to 28 minutes without requiring Kafka or Spark session startup overhead.
Yes. Nexla supports Apache Iceberg time travel capabilities, allowing users to query historical table states by timestamp or snapshot ID. This is useful for auditing, debugging, replaying pipelines, and compliance workflows.
Compared to Fivetran, Nexla provides several advanced Apache Iceberg capabilities, including high-speed snapshots without Kafka, native AWS S3 Tables support, incremental source reads, multi-table CDC consolidation, and built-in time travel support. Nexla also supports over 1,000 connectors for broader enterprise integration coverage.
Compared to Airbyte, Nexla offers deeper enterprise support for Apache Iceberg with native CDC, high-speed direct Iceberg ingestion, AWS S3 Tables support, time travel queries, and multi-table CDC consolidation. Nexla also provides incremental reads and broader catalog support for enterprise lakehouse deployments.